Automated Fact-Checking Tools for Security Technical Claims
Automated checks catch falsifiable facts, but experts must weigh context and evidence quality.
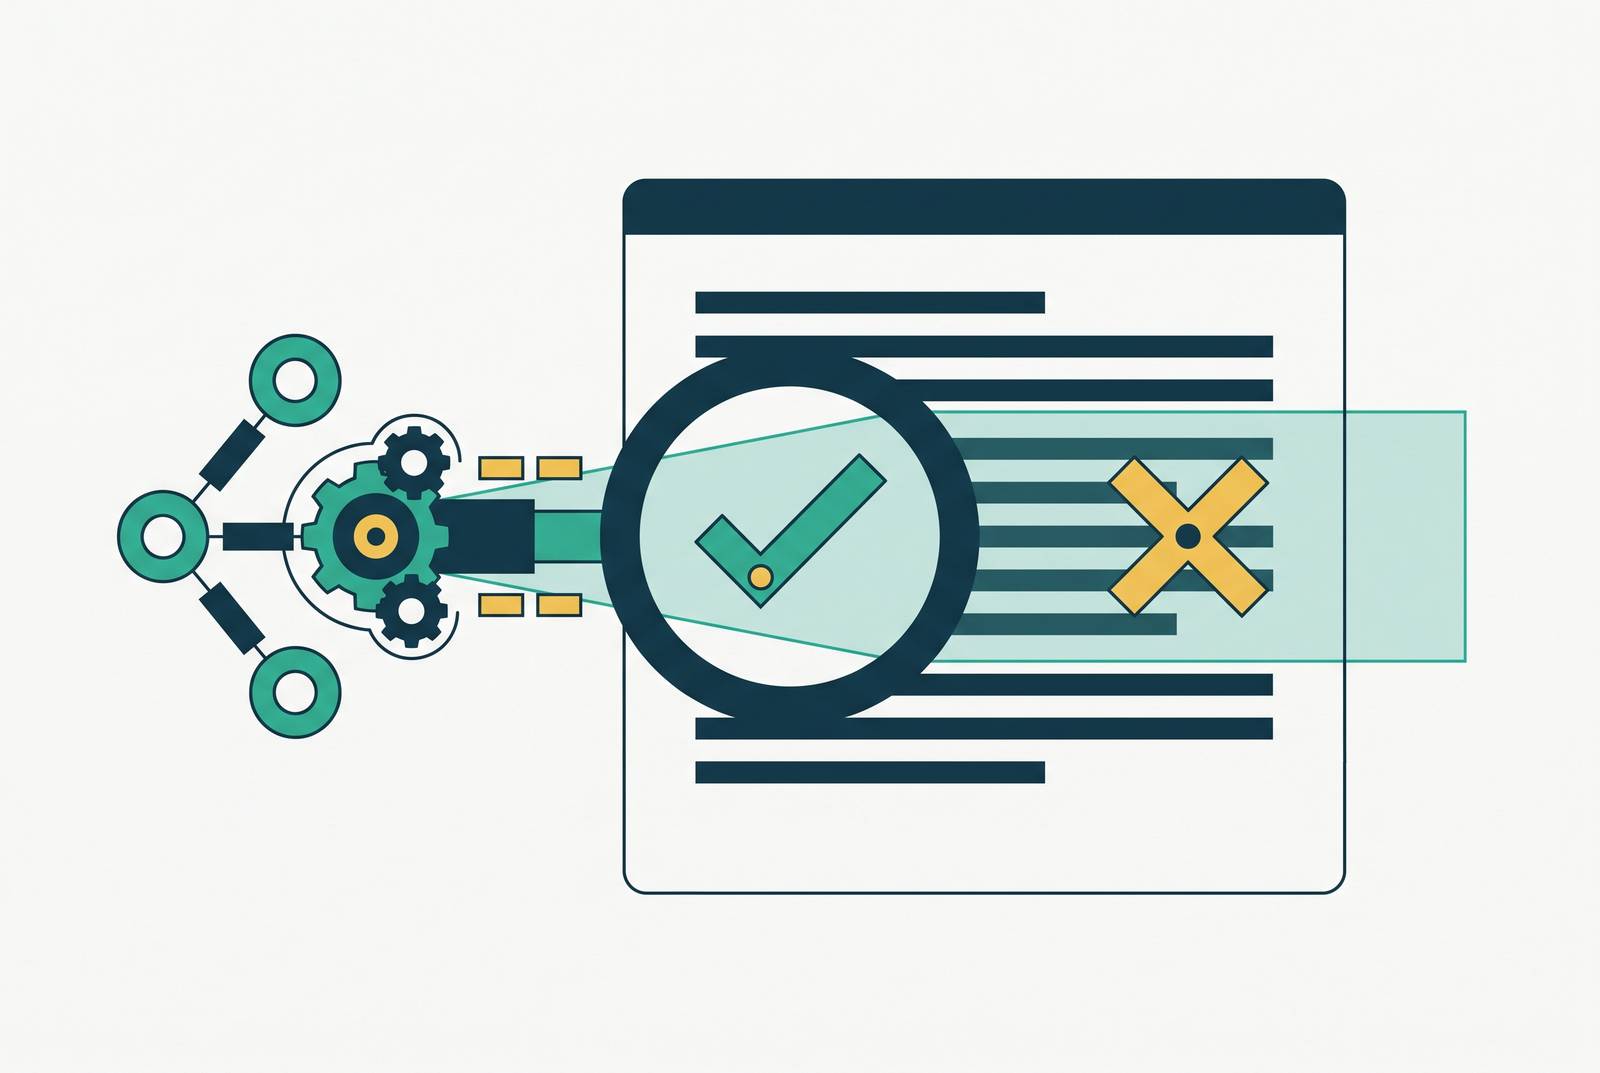
Automated fact-checking tools can bring structure and scale to the review of security technical claims, but they cannot give every claim a reliable verdict. A hybrid approach works best, with automation checking falsifiable facts and security experts judging the context, the quality of the evidence, and what the findings mean in use. This is meant to make clear what earns trust.
Why security technical claims fail before they reach a fact-checker
The gap between a security product’s marketed capability and its deployed performance does not require anyone to lie. It can arise because the people producing claims lack a systematic way to test them against operational reality. The promise goes into the communications, while the conditions that would limit it stay elsewhere. By the time a technical buyer reads the claim, that missing context has become a credibility problem. Better editing can polish the sentence, but it cannot supply the missing verification.
The “prophecy pattern” in AI SOC claims shows how this gap can protect itself. When tools fall short, the explanation most frequently offered is that buyers are not AI-ready. That shifts accountability from product immaturity to buyer psychology, making a disappointing result evidence against the customer. The internal feedback loop then loses the very information that could correct the claim.
Metric ambiguity creates a parallel problem without needing that defensive explanation. A claim such as “50% faster investigations” is unfalsifiable without a baseline, test conditions, and a measurement method. The number looks precise, but precision in the typography is not precision in the test. If nobody in the content pipeline is equipped to demand those missing details, the claim can circulate without ever becoming checkable.
Enterprises face a major challenge in determining the accuracy and credibility of threat intelligence reports, which makes fast action on warnings harder. What a vendor intends does not tell buyers whether they can trust the information. Both marketing and threat reporting need more verification as well as better prose. A response has to handle claims at the scale at which they are produced.
What automated fact-checking pipelines actually do, stage by stage
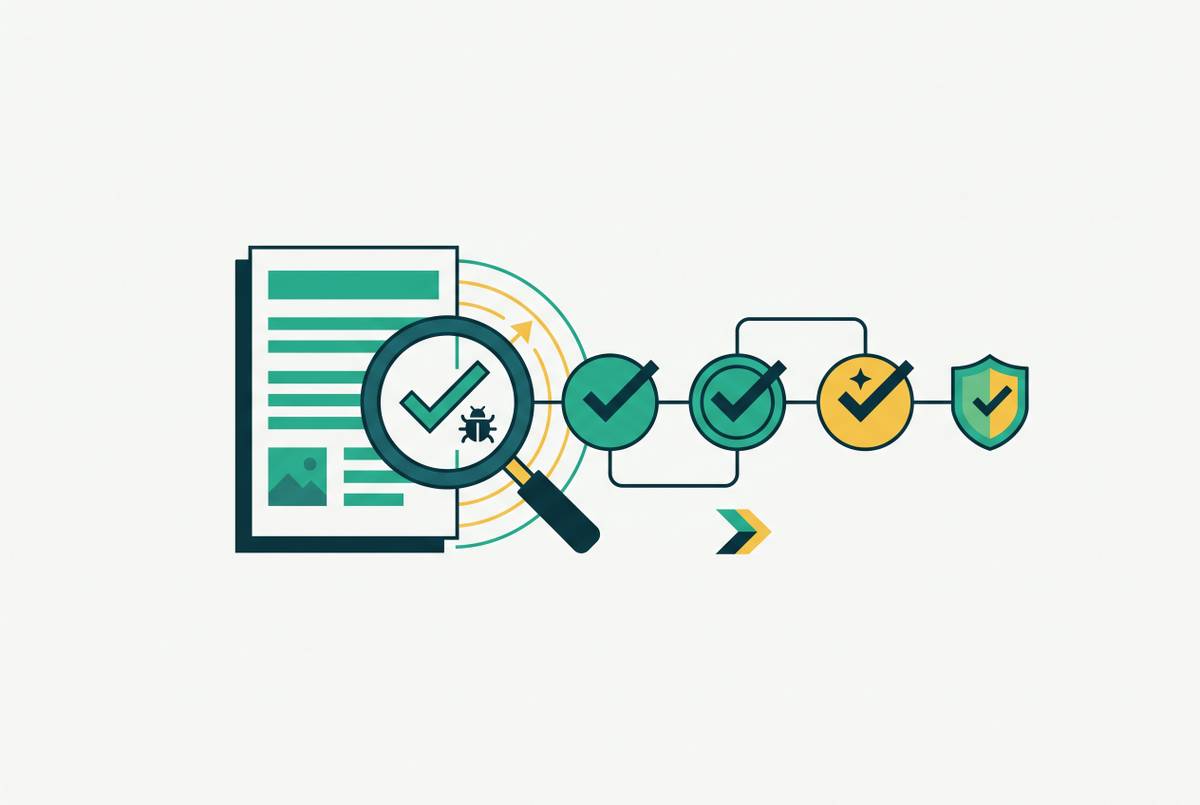
Vykopal et al.’s survey of generative LLMs in automated fact-checking describes a modular pipeline with distinct stages, namely claim detection, evidence retrieval, claim verification, and explanation generation. Each stage has its own question to answer and its own ways to fail. Detection identifies what is being asserted. Retrieval finds material that could bear on the assertion, while verification assesses whether that material supports or contradicts it. Explanation generation then makes the basis of the verdict readable.
Applied to a vendor white paper, the process begins by breaking the text into discrete, testable claims. At the evidence stage, the pipeline can look for answers in sources including CVE databases, primary research, and public benchmarks. Retrieved material supplies corroborating or contradicting evidence for the verification stage. The resulting verdict comes with an audit trail that the content team can act on. This is more useful than asking a model whether the whole document “looks accurate,” which gives a broad question the opportunity to receive a broad shrug.
An Input Ingestion Agent handles claim decomposition, and a Query Generation Agent prepares the queries. An Evidence Seeking Agent finds the evidence, and a Verdict Prediction Agent produces the verdict. Specialized components make the system easier to audit and improve incrementally. For example, a failure to retrieve relevant evidence is a different problem from a failure to reason correctly over evidence already found.
LLMs can work across these stages through claim normalization, sub-claim decomposition, evidence synthesis, and explanation generation. Their range makes them useful, but it also creates risks that a tidy pipeline diagram can conceal. Hallucination can introduce unsupported material, and limited faithfulness to retrieved evidence can weaken an otherwise well-sourced answer. Evaluation difficulties also complicate judgments about overall performance. The pipeline therefore provides a structure for checking claims whose verdicts still require scrutiny.
Which categories of security claims automated pipelines can adjudicate reliably
Reliability starts with the kind of claim entering the pipeline. Structured, falsifiable claims have ground-truth sources that retrieval can query directly. These include CVSS scores, CVE identifiers, IOC counts, integration coverage, and reported detection rates against named malware families. For such claims, a verdict can be auditable and reproducible because the assertion and the evidence have defined points of comparison. The crucial boundary is whether the claim specifies something that external evidence can actually settle.
Checking a reported detection rate against its source establishes something narrower than proving broad detection capability. Likewise, verifying an IOC count does not establish the accuracy and credibility of the threat intelligence containing it. These limits are reasons to keep the verdict attached to the precise claim.
Capability improvements become harder to adjudicate because their meaning often depends on what the sentence leaves out. Claims such as “reduces breach risk,” “autonomously investigates threats,” and “dramatically cuts alert volume” embed unspecified baselines, unmeasured conditions, or unresolved definitions. More retrieval cannot settle the comparison when no one has named the starting point. The mental sorting test is whether evidence could answer the claim as written or whether a person first has to decide what it means.
When AI sits between signal generation and human review without traceability, the alert count may fall because real signals are suppressed, even if detection fidelity has not improved. A pipeline checking the reported alert count could return an “accurate” verdict while missing that distortion entirely. The arithmetic would be right, but the implied benefit would remain unproven. In this case, the important question is not simply whether alert volume fell, but whether the fall represents the improvement being claimed.
How adversaries exploit the same pipeline architecture that defenders rely on
An automated fact-checking pipeline depends on external material to judge claims, so an adversary can target that material. This mirrors the attack surface of other retrieval-augmented systems. The architecture that gives the checker access to evidence also gives false evidence a route into its reasoning. Retrieval provides access to material of uncertain honesty.
Schlichtkrull’s position paper distinguishes “attacks by content” from classic prompt injection. Rather than hiding instructions in a document, an attacker supplies biased, misleading, or false information that an agent retrieves. Schlichtkrull demonstrates experimentally that LLM-based agents are vulnerable to this vector even when they are not vulnerable to instruction injection. The distinction matters because defenses aimed at hidden commands do not address false factual content. A document does not have to tell the model what to do if it can mislead the model about what is true.
Fluent prose and orderly formatting can carry disinformation just as easily as accurate, sourced claims. An automated fact-checking tool can thus get the verdict wrong even when the evidence looks clean. The threat is not confined to suspicious text that announces itself as an instruction.
Liu et al.’s survey groups attacks against automated fact-checking into three vectors. Adversarial claim attacks use forms such as paraphrasing or multi-hop claims to elicit incorrect verdicts. Adversarial evidence attacks inject manipulated evidence into the retrieval corpus, while adversarial claim-evidence pair attacks use synthetic pairs with superficial consistency and contradictory content. Together, these vectors show that reliability can be attacked at the claim, the evidence, or their relationship. A security vendor’s deployment that ignores evidence injection will be only as reliable as the corpus it queries, and that corpus is neither static nor neutral.
Where human domain judgment remains the non-negotiable check
Human review remains a structural part of this system as the models improve. Some claims require decisions about meaning and conditions before any evidence comparison can be useful. Adversarial evidence also means someone must judge whether a source can be trusted. These are different tasks from matching a claim to a retrieved passage. In contested security contexts, domain expertise is the deciding variable.
Schlichtkrull’s proposed defense requires an agent to “forage for additional evidence to support or refute claims in found documents, and then decide whether the claims or the refuting evidence is more trustworthy”. If sources conflict, the system must assess their credibility. In contested security contexts, a human still has to make that judgment. Additional retrieval can support the decision, but it does not remove the need to make it.
Human-in-the-loop mechanisms at inference time nevertheless face a scaling ceiling because they depend heavily on manual labor. Broad deployment can therefore be costly, which makes the placement of review more important than its mere presence. Sending every structured fact to an expert wastes the advantage of automation. Treating every uncertain capability claim as a routine evidence match wastes the expert’s absence in a more dangerous way.
The vendor proof-of-concept process offers a concrete model for that division. Success criteria written before the first vendor conversation give reviewers an objective frame, with each criterion expressed through a number, a format, or a binary condition. Automated pipelines can partially populate that frame, but domain judgment must define it. For probabilistic claims such as “reduces breach risk,” “improves detection fidelity,” and “autonomously resolves incidents,” a security expert must interrogate the unstated baseline and deployment conditions. The expert must also distinguish a genuine improvement from suppression, so that passing the test means something operationally useful.
What a working hybrid verification approach looks like in security content production
A defensible content workflow assigns claim types to the methods suited to them. Structured, falsifiable claims go through automated checking, while human domain experts review claims that are probabilistic or depend on context. This avoids applying one method uniformly simply because it is available. Neither method has to pretend to do the other’s job.
That division starts with getting claim decomposition right and choosing the right sources. Material based on live threat intelligence and checked against primary sources gives the workflow claims with substance to check. Domain fluency matters at this early stage because a poorly framed sub-claim can send retrieval toward evidence that answers the wrong question. Human expertise is therefore part of the verification architecture from the outset.
Security practitioners cite independent expert research and customer case studies as among the top influences on vendor selection, while generic blog posts do not appear on that list. Verification is therefore more than quality control behind the scenes. It shapes the kind of material that can show buyers a basis for confidence. Content architecture and verification architecture are inseparable when the content’s value depends on whether its claims survive scrutiny.
A content studio built on security domain expertise is an organizational expression of this hybrid approach. Its foundation supports accurate decomposition, suitable evidence selection, and reliable human review where automation reaches its ceiling. By contrast, general content marketing methods alone do not supply the domain judgment needed to evaluate security claims. The working model combines scalable checks with expertise at the points where meaning, credibility, and operational consequences remain unresolved. That is how automated fact-checking becomes useful infrastructure rather than a faster way to put a checkmark beside an uncertain claim.